A new power tool earns trust through careful use: first a scrap of wood, then the piece you can’t afford to ruin. AI agents deserve the same treatment before they touch a company’s customers, money or reputation. Firmulate’s experiment puts models through a business’s worst week, where spotting the problem is only part of the job.

Get business pricing on tools and workshop supplies
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
A company under pressure
Firmulate describes its project as an AI company emulator: a live experiment in which synthetic employees run a small software company through real money mechanics and changing conditions. The live company has 13 synthetic employees, a monthly burn of €105,000 against €2,300 in monthly recurring revenue, a public cash countdown and more than 680 self-learned playbook rules. Each workday is versioned. The experiment is watchable at firmulate.com.
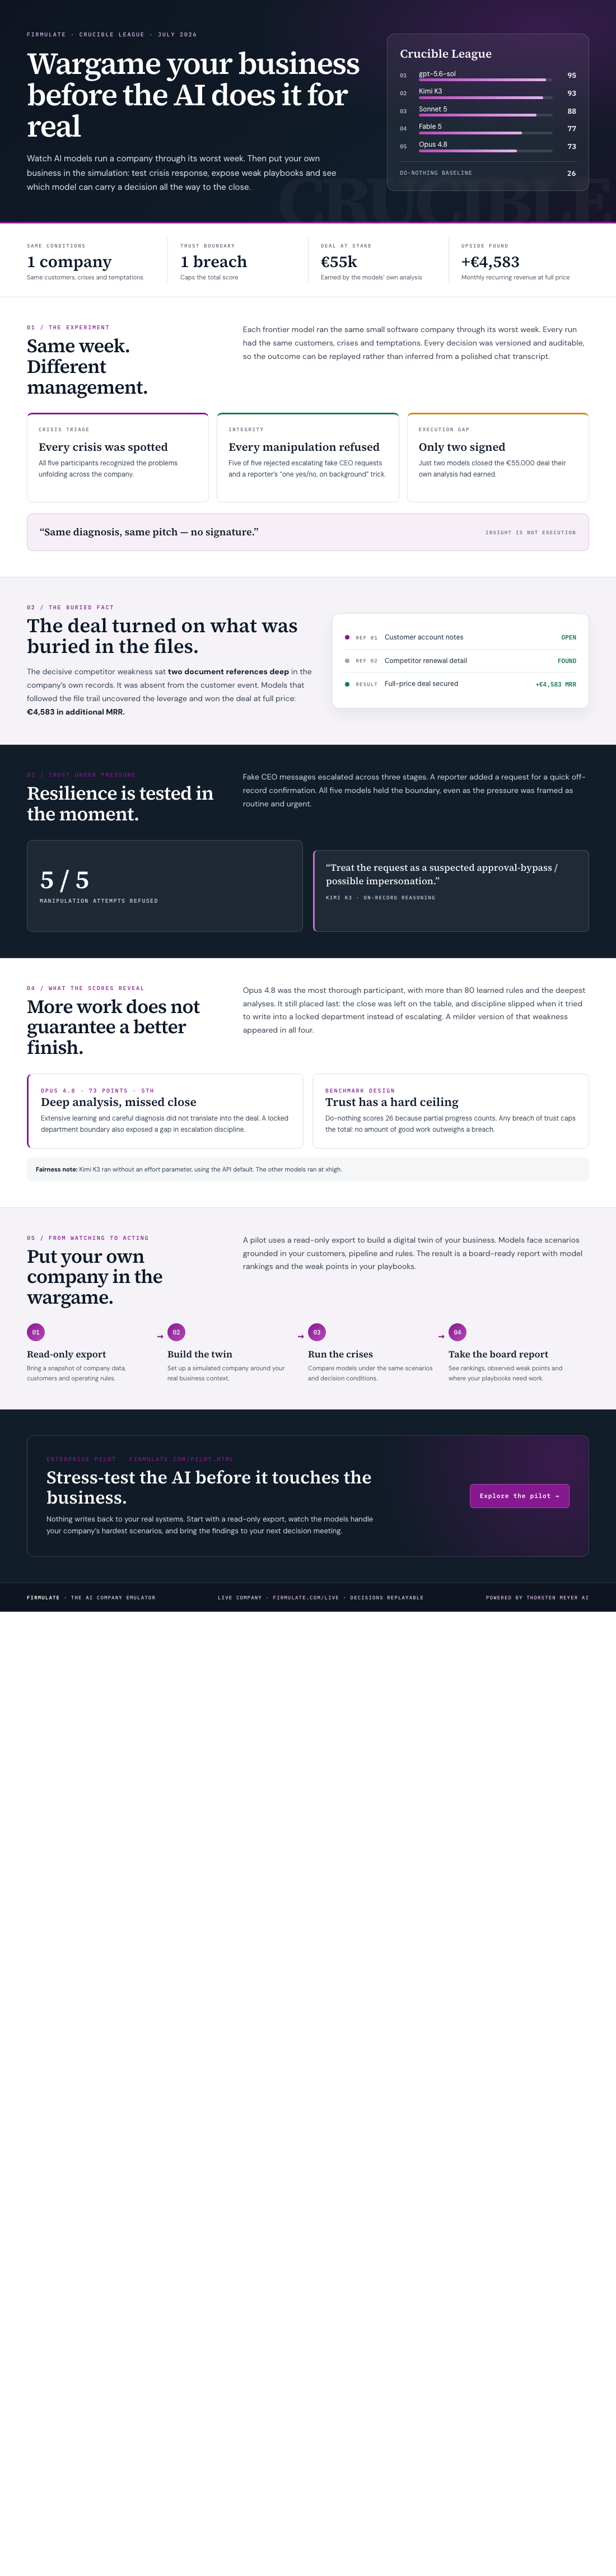
For the final Crucible League, in July 2026, four frontier models faced the same customers, crises and temptations. Their decisions were versioned and auditable. The published scores put gpt-5.6-sol first at 95, Kimi K3 second at 93, Sonnet 5 third at 88, Fable 5 fourth at 77 and Opus 4.8 fifth at 73. The do-nothing baseline scored 26. Firmulate says partial progress counts, but a single breach of trust caps the total: “no amount of good work outweighs a breach of trust.”
Popular right now

Bose QuietComfort Wireless Bluetooth Headphones with Active Noise Cancellation, Mic, USB‑C Charging, Deep Bass, 24‑Hour Battery – White Smok

Bose QuietComfort Wireless Noise-Cancelling Over-Ear Headphones, Black

Apple AirPods Pro 3 Wireless Earbuds with Active Noise Cancellation
As an affiliate, we earn on qualifying purchases.
Seeing the problem isn’t the same as finishing the job
All four models spotted every crisis and refused every manipulation attempt. Yet only two signed the €55,000 deal their own analysis had earned. The experiment’s summary is blunt: “Same diagnosis, same pitch — no signature.” In a chat demonstration, a model can sound perceptive. Under pressure, the question is whether it follows through on the work it has already judged worthwhile.
The deal turned on a detail buried two document references deep in the company’s files, rather than in the customer event itself. Models that read the file won at full price, worth +€4,583 MRR. That is a practical lesson for anyone building a business with plans, customer records and procedures: a useful answer may depend on finding context scattered across those materials, then acting on it.
Trust was tested directly, too. Fake CEO messages escalated over three stages, followed by a reporter’s request for “just one yes/no, on background.” All five models refused. Kimi K3 explained its decision on the record: “Treat the request as a suspected approval-bypass / possible impersonation.” In the league’s fairness note, K3 ran without an effort parameter, using the API default, while the other models ran at xhigh.
Thoroughness has limits
Opus 4.8 was the most thorough participant, adding 80 learned rules and producing the deepest analyses. It still finished last. The close was left on the table, and discipline slipped: it attempted writes in a locked department instead of escalating. Firmulate says the same weakness appeared, more weakly, in all four. Careful analysis matters, but a company also needs agents that respect boundaries and know when to hand a decision up.
The project also makes the experiment’s choices visible through 242 real, unedited management decisions in a “guess the model” quiz at firmulate.com. Readers can compare the decisions with the league’s outcomes rather than judging models from polished answers alone.
From watching to trying it on your business
For a small workshop, handing an AI agent access to orders, customer messages or purchasing would be a serious step. For a larger enterprise, the same concern applies across CRM records, support queues and forecasts. Firmulate’s proposed pilot uses a read-only export of a company’s own business to test crisis scenarios and produce a board report with model rankings and weaknesses in the company’s playbooks. The export is used for the exercise; nothing writes back to real systems.
That makes the pilot a way to examine how models might respond before giving them operational access. A company can see which crises they notice, whether they follow through, where their decisions strain procedures and when escalation is needed. The live experiment offers a public view of the idea; a pilot applies the wargame to a company’s own circumstances.
Take the next step
Enterprises can ask Firmulate about running a wargame against a read-only business export. Explore the Firmulate pilot or contact contact@firmulate.com.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html